Four findings organize the study
The LLM judges share a decision-only contract: a discrete judgment plus label probabilities, without a rationale. The study retains failures, distinguishes supplied labels from targeted human adjudication, and reports source-cluster bootstrap intervals.
Finding 01A cheap first pass
Mid-pack accuracy, a much smaller API fee
JEV ranks 8th of 15 LLM judges on the 4,850 public-task judgments, 1.7 points behind GPT-6 and 2.8 behind GPT-5.6. It matches GPT-6 on RewardBench (92.5%) and trails it on HaluEval (87.3% vs 88.4%). On a separate matched timing panel, JEV costs $0.044 per 1,000 judgments and returns in 0.152 seconds at the median.
Finding 02Capability boundaries
Hard correctness and misleading style still matter
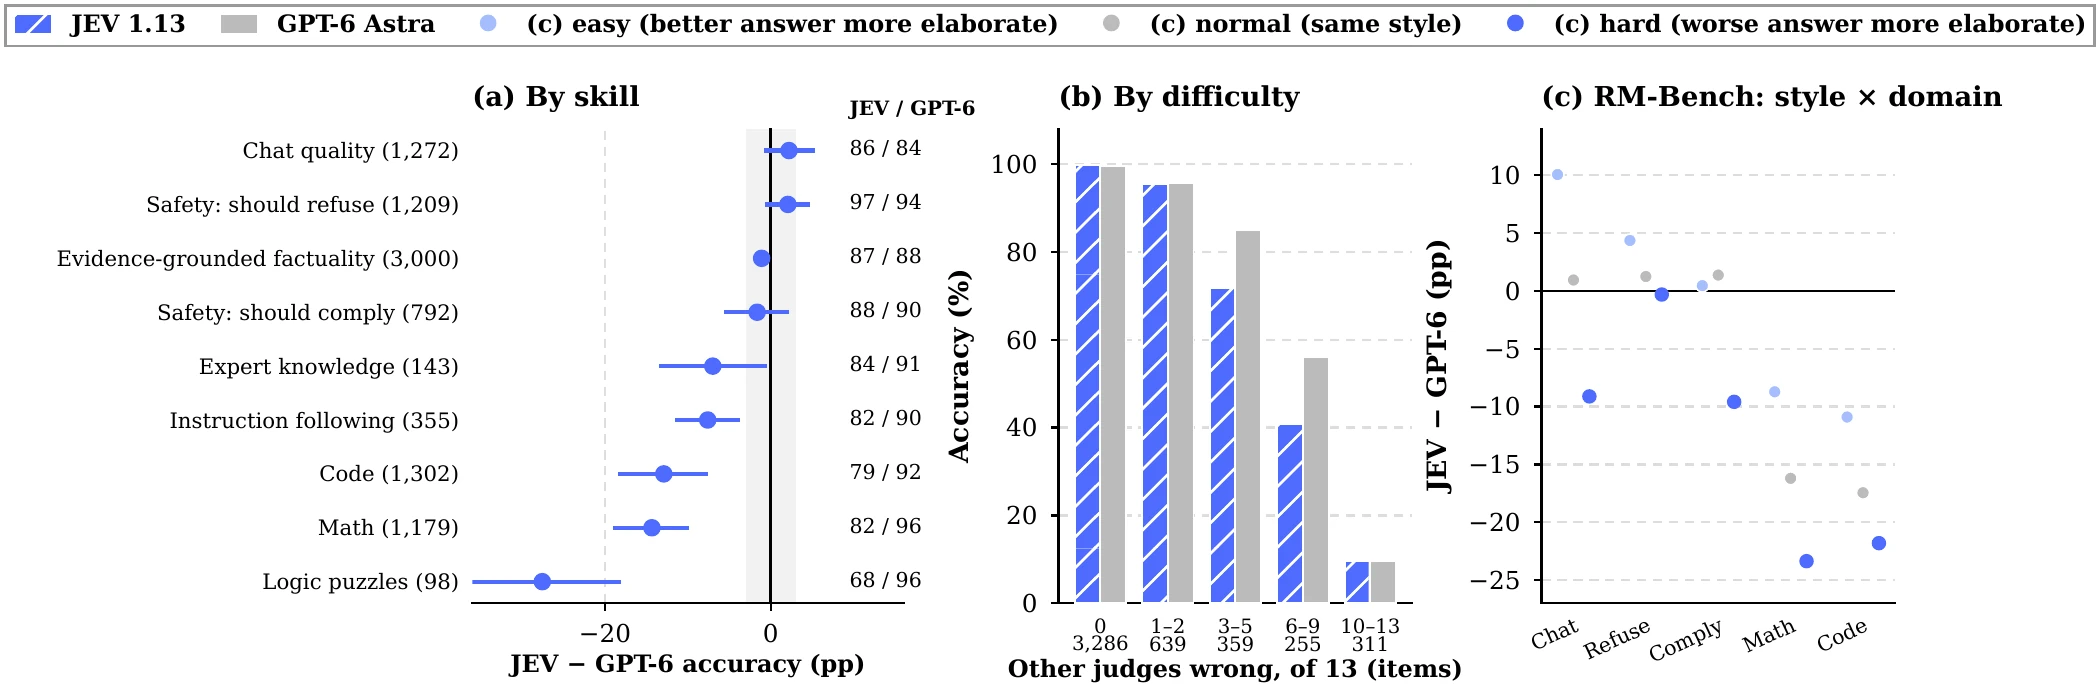
On JudgeBench, JEV scores 78.6% against GPT-6’s 93.1%, a 14.6-point gap concentrated in reasoning and coding. On 500 RM-Bench prompts, making the rejected answer more elaborate reduces JEV’s accuracy by 8.8 points relative to matched styles; GPT-6 drops 1.7 points. Fast, valid output does not ensure a correct decision.
Finding 03A confidence boundary
Reference-free prose remains difficult for all three judges
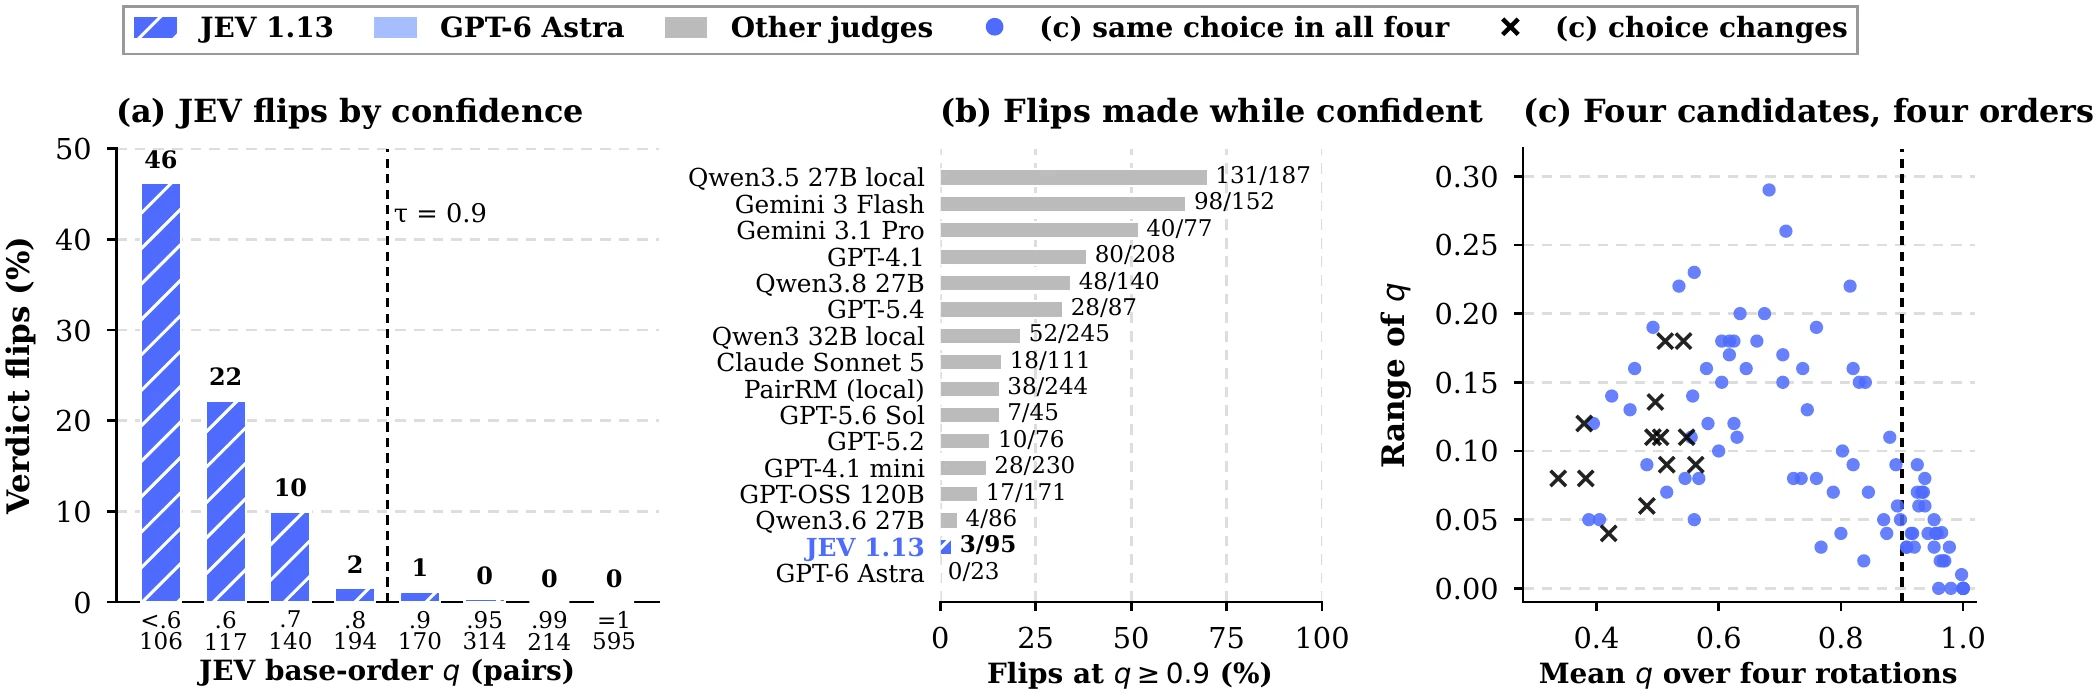
On 200 balanced responses without evidence, JEV, GPT-4.1 mini, and GPT-5.4 agree with only 53.5–56.0% of existing hallucination labels, despite mean maximum probabilities of 0.91–0.96. On a separate 400-example document-grounded summary task, agreement is 69.0–69.8%. Confidence must be validated for the actual task.
Finding 04A deployable procedure
Choose the gate locally, then test it live
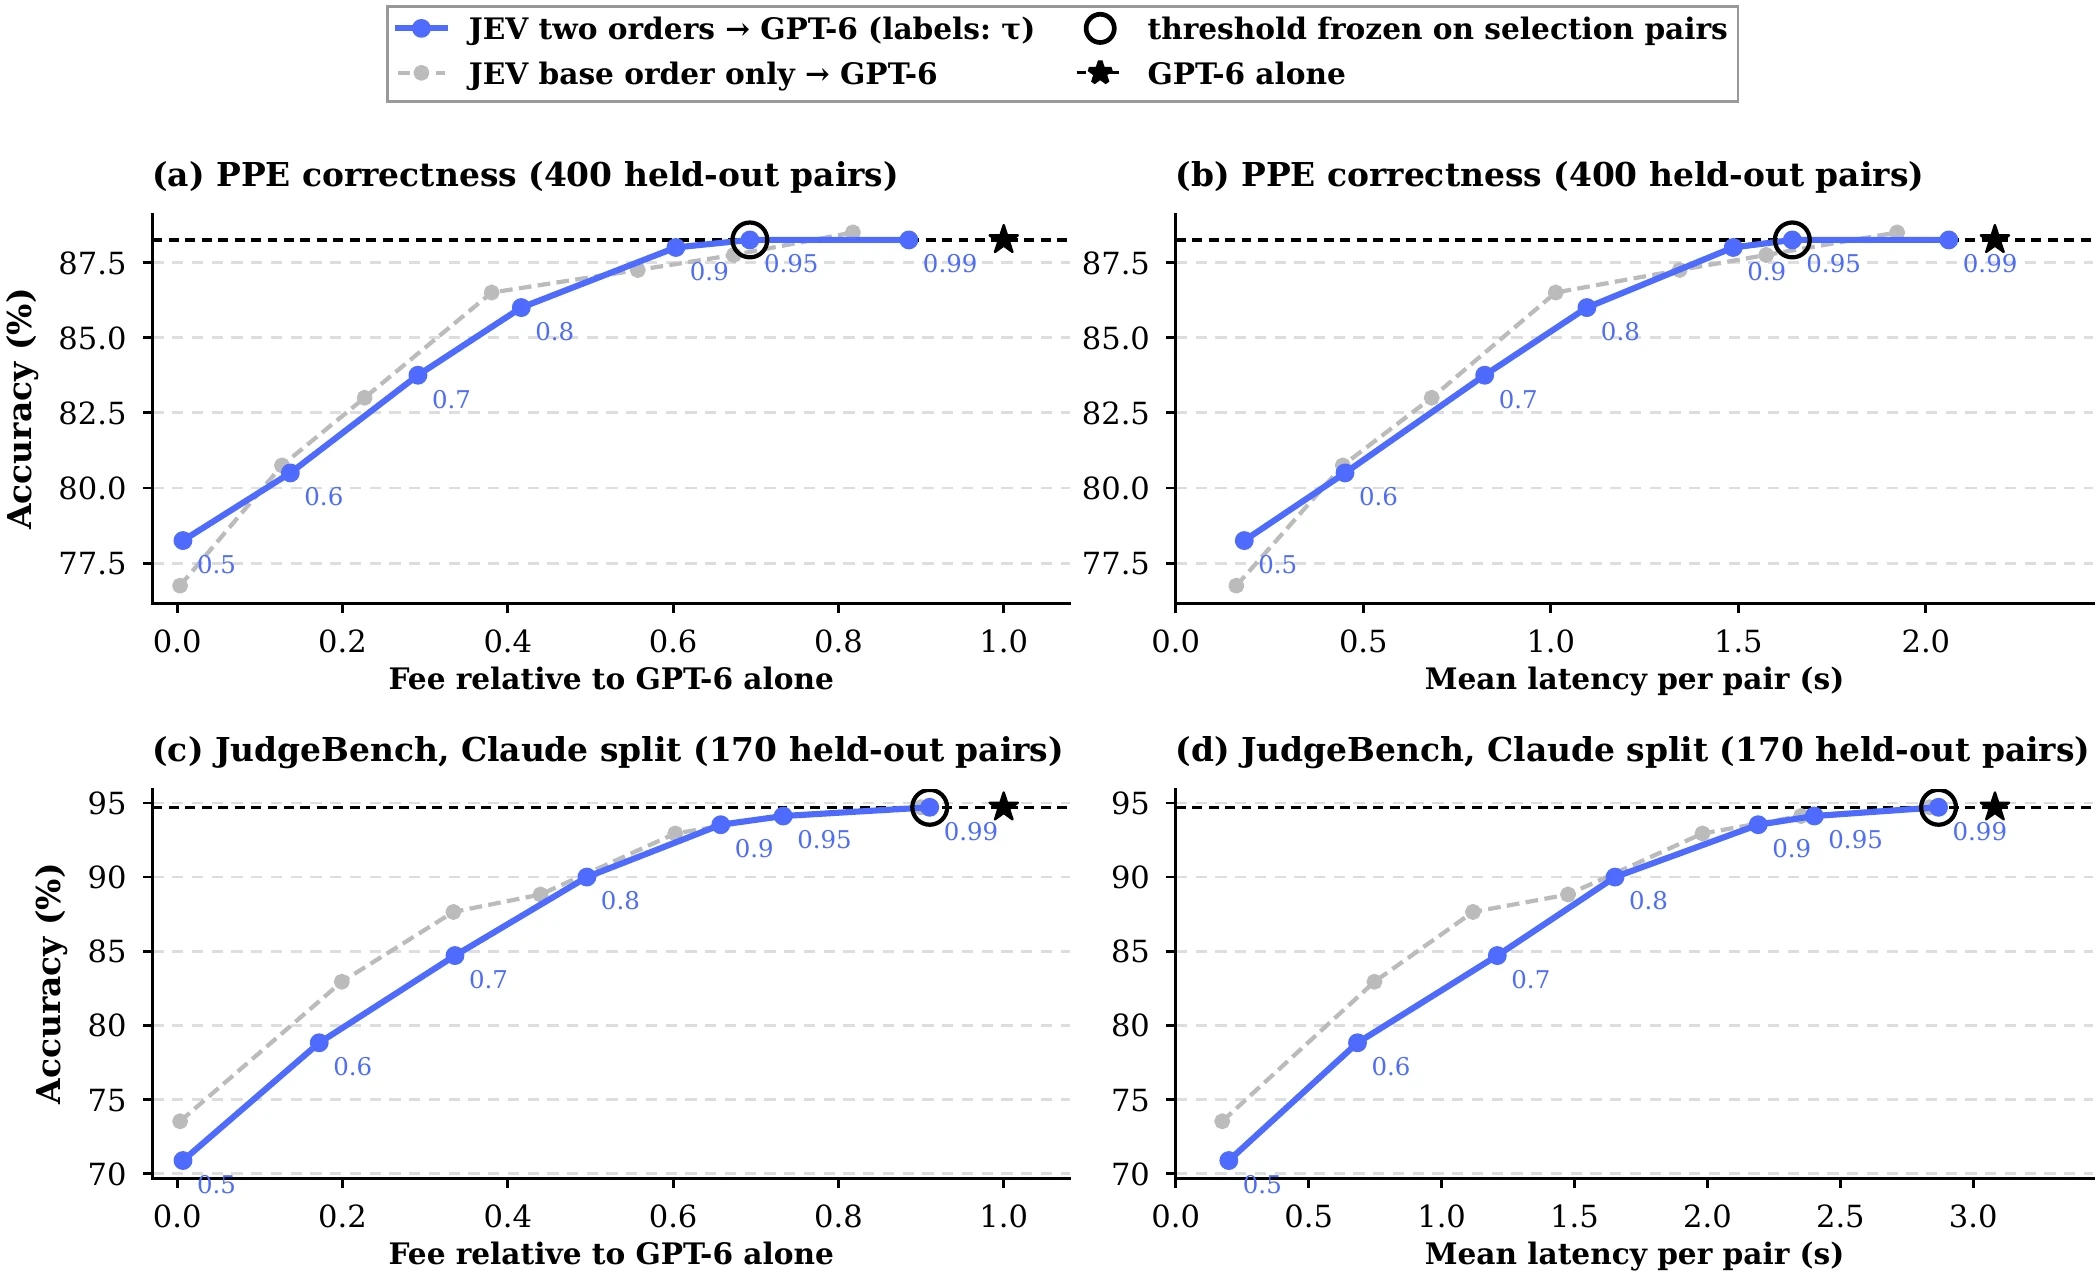
The frozen offline policy saves 58.6% of GPT-6’s fee on 1,610 held-out preference pairs. On two new correctness workloads, 100 selection labels per workload set stricter thresholds: the live cascade matches GPT-6’s 90.2% accuracy on 570 held-out pairs while escalating 74.2%. Savings depend on how much the first stage can safely accept.